“But we already have a search.”
That statement is almost always true. The documents are in local directories or SharePoint, they have been indexed, there is a search field, and anyone typing into it receives results. Yet in those same businesses, someone still walks down the corridor to ask a colleague about something that is written in a document.
This is not a contradiction. It is a characteristic of the technology.
Character strings and meaning
Full-text search compares character strings. It takes what you type and looks for the same sequence of letters in the documents. It is a reliable, fast and very old technique, with one condition: the word has to be there.
But people do not ask about words. They ask about meanings.
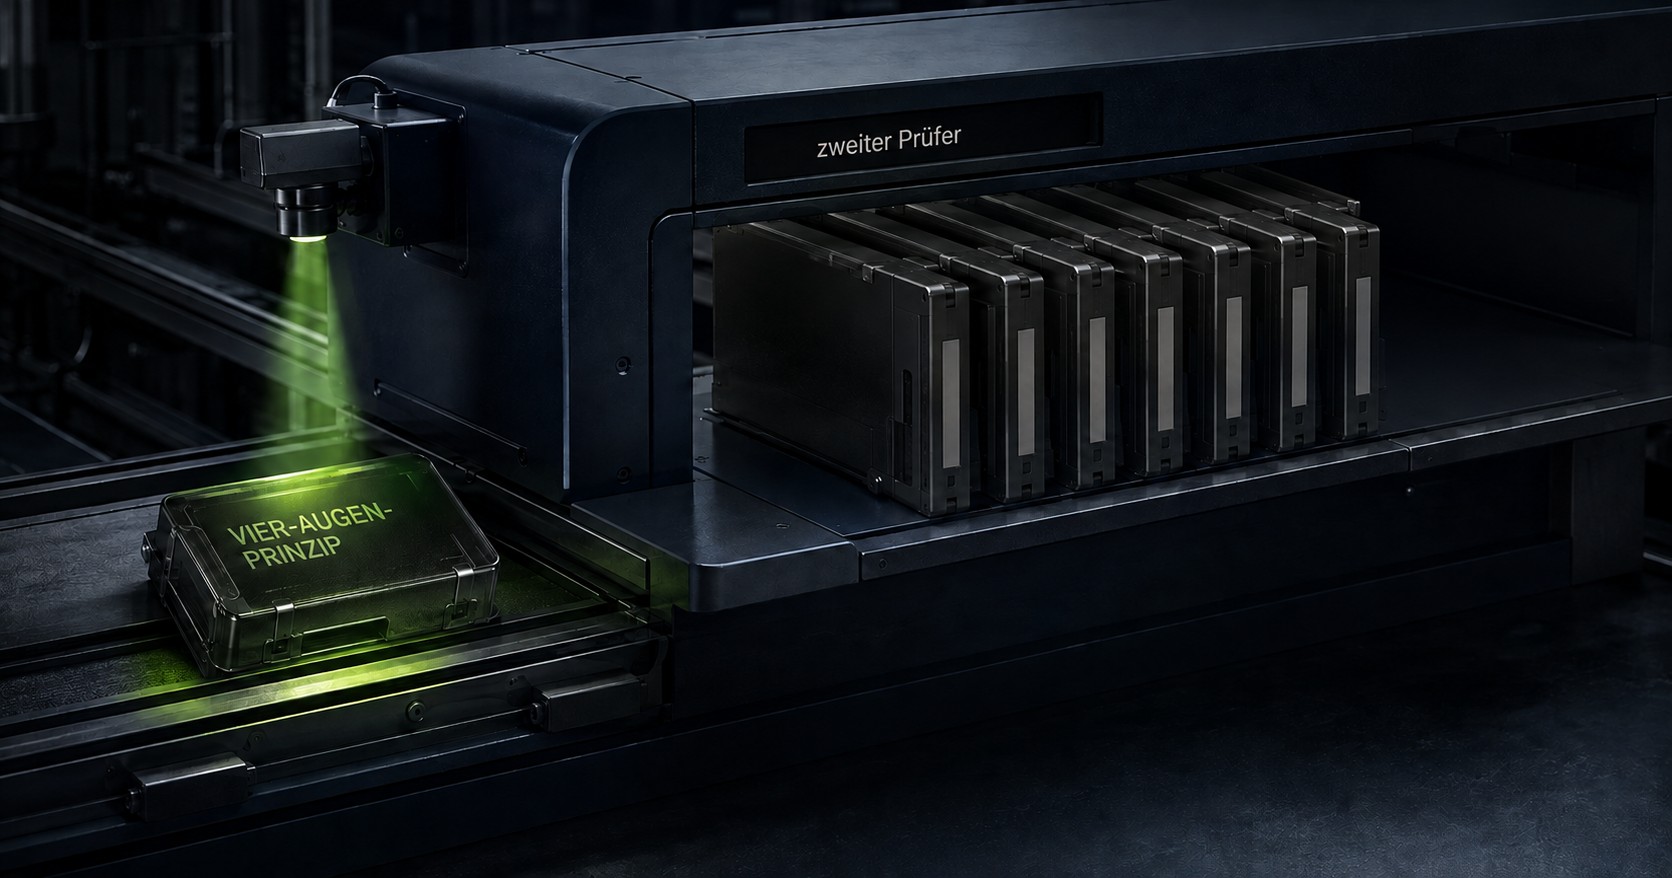
Here is an example we measured at NXTGN. The question was: “When is a second reviewer required?” The answer was in the collection, in a quality guideline. However, the term used there was “Vier-Augen-Prinzip” — the dual-control principle.
Not a single document contained “zweiter Prüfer”, the German wording for “second reviewer” used in the question.
The search returned nine results. The guideline was not among them. Not far down the list — not there at all.
The loss nobody notices
This is where the real problem lies, and it is a business problem.
A search that finds nothing looks like an empty archive. It reports no error. It does not say “that word does not appear anywhere; perhaps a different term is used”. It returns nine irrelevant results and leaves the person looking at them to draw a conclusion. That conclusion is almost always: It must not be in there.
After that, the usual things happen. Someone asks a colleague. Someone makes a decision on instinct. Someone recalculates something that was already calculated four years ago.
The investment in digitisation has been made. The benefit remains invisible, not simply because it fails to materialise, but because nobody notices where it fails to materialise. You cannot count how often a search failed to find something that was there.
Three reasons the word is not there
The case above is not an oddity. There are three reasons for it, and they rarely occur in isolation.
The same thing has different names elsewhere. Maintenance says “Laufrad”, purchasing says “Impeller”, and the drawing says “Pos. 14”. Which word someone uses depends on their department, the site and the generation of the person who wrote the document. A confusion of languages — and it is the normal state of affairs.
Abbreviations are local. “L7” means Line 7 in one business and a warehouse in another. Neither document spells it out because the meaning was obvious to its authors.
And the language changes. The manufacturer’s documentation is in English, but the question is asked in German. The character string is not merely different; it comes from a different language altogether. A separate article explains why we do not solve this by translating.
What meaning-based search can do
That is why NXTGN AI CORE uses two search approaches. Keyword search remains, because it is unbeatable when the word is present: for part numbers, standards identifiers and proper names. Alongside it, a second search compares sentences by meaning rather than words.
How it works takes some explanation and is not the focus of this article. What matters is that two sentences with the same meaning end up close together, even if they do not share a single word. Both results lists are merged, without the person searching noticing.
This solves the case of the English manual. It does not solve the dual-control example.
And what it cannot do
An AI model that compares meanings has learned meanings — just not yours. The fact that “Vier-Augen-Prinzip” means exactly what another person calls “zweiter Prüfer” in your business is not a universal truth. It is a definition someone in your company agreed on, often years ago, usually without writing it down.
This is the part no model supplies. It has to come from the company.
In practice, that means a glossary: a term, its synonyms, its abbreviations, and an indication of which name is the standard. In the example above, it took just one entry: “Vier-Augen-Prinzip”, with “zweiter Prüfer” listed alongside it. The same question then returned sixteen results, including the guideline.
One entry. Five minutes of work for someone who knows the subject.
Why a result must explain how it was found
An expanded match is not the same as a direct match. It relies on an equivalence defined by a person, and that equivalence may be wrong.
That is why NXTGN AI CORE states it: “Found via: zweiter Prüfer = Vier-Augen-Prinzip.” In English, that means “second reviewer = dual-control principle”. Anyone reading it can immediately see why the document appears in the list, and challenge the equivalence if it does not apply in their area.
A search that silently expands its terms is more convenient and less useful. It deprives the reader of the chance to spot the one error that only they can identify.
My conclusion
Digitising information and making it findable are two different undertakings, and the first is easier. Scanning a folder is a project with an end. Ensuring that someone can find its contents four years later is a task without an end.
Much of it can be left to the system: crossing language boundaries, handling different phrasing and sorting by meaning. But nobody can decide for you what something is called in your business. That is where digitisation ends and knowledge work begins.
The folder on the shelf was never the problem, and neither is the scanned folder. The answer is in it. The question simply uses a different word.